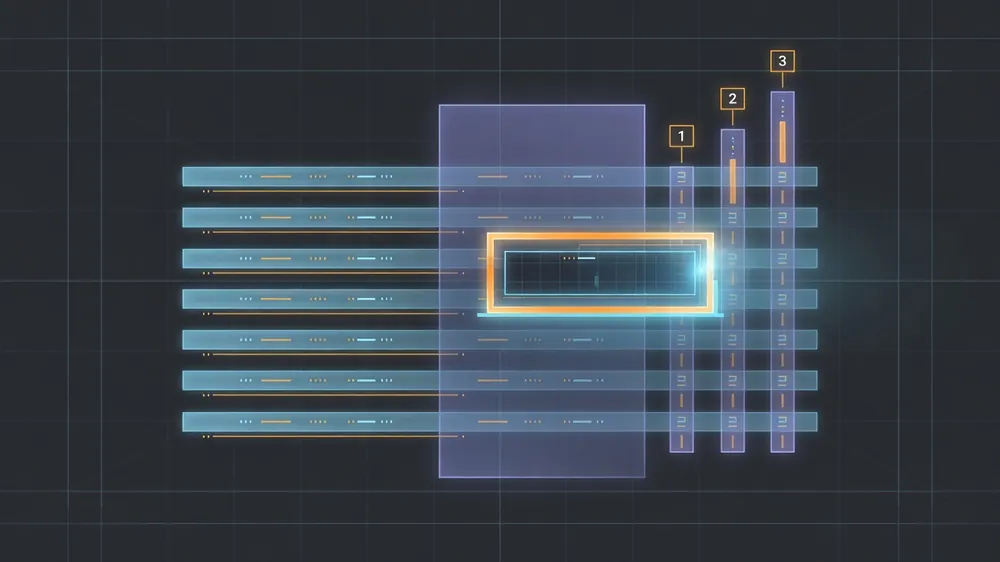
SQL window functions allow performing analytical calculations across row partitions without collapsing individual rows, replacing complex self-joins with clean, readable queries.
This post is the mental model I keep, plus the queries I paste into real work. Postgres, BigQuery, Snowflake, and modern MySQL all support the same core syntax. Dialects differ on small extras, not on the idea.
One idea: a window is a frame over rows you already have
A normal aggregate collapses rows:
SELECT region, SUM(amount) AS total
FROM sales
GROUP BY region;
You lose the line-level detail. A window function computes an aggregate or ranking per row, while still returning every row:
SELECT
  region,
  order_id,
  amount,
  SUM(amount) OVER (PARTITION BY region) AS region_total
FROM sales;
Each order stays. You also get the region total next to it. That is the whole trick.
The clause that defines the window is OVER (...). Inside it you usually care about three pieces:
PARTITION BY- reset the calculation when this key changes (like a softGROUP BY).ORDER BY- order rows inside each partition (required for ranks, lag, running sums).- Frame - which neighbor rows count for the current row (
ROWS BETWEEN ...). Defaults matter; more on that below.
If you remember only one sentence: partition says who you compete with, order says in what sequence, frame says how far the calculator looks.
Sample data for the rest of the post
CREATE TABLE orders (
  order_id   int PRIMARY KEY,
  customer_id int,
  region     text,
  order_date date,
  amount     numeric
);

INSERT INTO orders VALUES
  (1, 101, 'west',  '2025-11-01', 120),
  (2, 101, 'west',  '2025-11-15',  80),
  (3, 101, 'west',  '2025-12-01', 200),
  (4, 202, 'east',  '2025-11-03',  50),
  (5, 202, 'east',  '2025-11-20',  50),
  (6, 202, 'east',  '2025-12-10', 300),
  (7, 303, 'west',  '2025-11-08',  90),
  (8, 303, 'west',  '2025-12-05', 110);
Tiny on purpose. Read the results out loud once and the functions stop feeling magical.
ROW_NUMBER: pick one row when ties exist
ROW_NUMBER() assigns a unique sequence inside the partition. Ties in the ORDER BY still get different numbers. That is what you want for "exactly one winner."
Pattern: latest order per customer
WITH ranked AS (
  SELECT
    order_id,
    customer_id,
    order_date,
    amount,
    ROW_NUMBER() OVER (
      PARTITION BY customer_id
      ORDER BY order_date DESC, order_id DESC
    ) AS rn
  FROM orders
)
SELECT order_id, customer_id, order_date, amount
FROM ranked
WHERE rn = 1;
| order_id | customer_id | order_date | amount |
|---|---|---|---|
| 3 | 101 | 2025-12-01 | 200 |
| 6 | 202 | 2025-12-10 | 300 |
| 8 | 303 | 2025-12-05 | 110 |
Notes that save you pain later:
- Always add a tie-breaker (
order_id DESChere). Without it, which row isrn = 1is undefined when two dates match. - Filter on the window result in a CTE or subquery.
WHERE ROW_NUMBER() ...is illegal in standard SQL becauseWHEREruns before window functions. - Same pattern for "first event per user," "current subscription row," "latest deploy per service."
RANK and DENSE_RANK: when ties should share a place
ROW_NUMBER is unique. RANK and DENSE_RANK allow ties.
SELECT
  region,
  order_id,
  amount,
  RANK()       OVER (PARTITION BY region ORDER BY amount DESC) AS rnk,
  DENSE_RANK() OVER (PARTITION BY region ORDER BY amount DESC) AS dense_rnk,
  ROW_NUMBER() OVER (PARTITION BY region ORDER BY amount DESC, order_id) AS rn
FROM orders
ORDER BY region, amount DESC, order_id;
For east, amounts 300, 50, 50:
| amount | RANK | DENSE_RANK | ROW_NUMBER |
|---|---|---|---|
| 300 | 1 | 1 | 1 |
| 50 | 2 | 2 | 2 |
| 50 | 2 | 2 | 3 |
Then the next distinct value would be:
- RANK: jumps to 4 (skips after a two-way tie at 2)
- DENSE_RANK: goes to 3 (no gaps)
- ROW_NUMBER: already used 1, 2, 3 regardless of ties
When to use which:
| Need | Function |
|---|---|
| One row per group, no ties allowed in the result | ROW_NUMBER + filter rn = 1 |
| Leaderboard that can skip places after ties | RANK |
| Leaderboard with no gaps in place numbers | DENSE_RANK |
| Top 3 amounts even if more than 3 rows tie | filter DENSE_RANK() <= 3 |
Pattern: top 2 orders by amount in each region
WITH ranked AS (
  SELECT
    *,
    DENSE_RANK() OVER (
      PARTITION BY region
      ORDER BY amount DESC
    ) AS place
  FROM orders
)
SELECT region, order_id, amount, place
FROM ranked
WHERE place <= 2
ORDER BY region, place, order_id;
LAG and LEAD: previous and next without a self-join
LAG(expr, n) looks n rows back inside the partition (after ORDER BY). LEAD looks forward. Default n is 1.
Pattern: period-over-period change per customer
SELECT
  customer_id,
  order_date,
  amount,
  LAG(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date
  ) AS prev_amount,
  amount - LAG(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date
  ) AS delta,
  ROUND(
    100.0 * (amount - LAG(amount) OVER (
      PARTITION BY customer_id
      ORDER BY order_date
    ))
    / NULLIF(LAG(amount) OVER (
      PARTITION BY customer_id
      ORDER BY order_date
    ), 0),
    1
  ) AS pct_change
FROM orders
ORDER BY customer_id, order_date;
For customer 101:
| order_date | amount | prev_amount | delta | pct_change |
|---|---|---|---|---|
| 2025-11-01 | 120 | NULL | NULL | NULL |
| 2025-11-15 | 80 | 120 | -40 | -33.3 |
| 2025-12-01 | 200 | 80 | 120 | 150.0 |
The first row has no previous value, so LAG returns NULL. That is expected. Use LAG(amount, 1, 0) if you want a default instead of NULL (Postgres and many engines support the third argument).
Pattern: days since last order
SELECT
  customer_id,
  order_date,
  order_date - LAG(order_date) OVER (
    PARTITION BY customer_id
    ORDER BY order_date
  ) AS days_since_prev
FROM orders;
On Postgres, date subtraction gives an integer day count. Elsewhere you may need DATEDIFF or DATE_DIFF.
Running totals: SUM with an ordered frame
This is the classic "bank balance" or "YTD revenue" query.
SELECT
  customer_id,
  order_date,
  amount,
  SUM(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date, order_id
    ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
  ) AS running_total
FROM orders
ORDER BY customer_id, order_date;
Customer 101:
| order_date | amount | running_total |
|---|---|---|
| 2025-11-01 | 120 | 120 |
| 2025-11-15 | 80 | 200 |
| 2025-12-01 | 200 | 400 |
Why spell out the frame?
For SUM / AVG / COUNT with ORDER BY, engines default to a RANGE frame from the start of the partition through the current peer group (same sort key). If two rows share the same order_date, both can pick up each other's amount in the "running" total, which surprises people.
ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW is physical row order: each row adds only itself once, in the order you specified. Prefer ROWS for true running totals. Keep a unique ORDER BY (add order_id) so the sequence is stable.
Moving average (last 3 orders):
SELECT
  customer_id,
  order_date,
  amount,
  AVG(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date, order_id
    ROWS BETWEEN 2 PRECEDING AND CURRENT ROW
  ) AS avg_last_3
FROM orders
ORDER BY customer_id, order_date;
Early rows have fewer than three observations. That is fine; the average is over whatever exists in the frame.
Partition only: share of total without a join
You do not always need ORDER BY.
SELECT
  region,
  order_id,
  amount,
  SUM(amount) OVER (PARTITION BY region) AS region_total,
  ROUND(
    100.0 * amount / SUM(amount) OVER (PARTITION BY region),
    1
  ) AS pct_of_region
FROM orders
ORDER BY region, order_id;
Same idea for amount / SUM(amount) OVER () when the denominator is the whole result set (empty OVER()).
FIRST_VALUE and NTH_VALUE: anchor a baseline
Pattern: each row vs the customer's first order amount
SELECT
  customer_id,
  order_date,
  amount,
  FIRST_VALUE(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date, order_id
    ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING
  ) AS first_order_amount,
  amount - FIRST_VALUE(amount) OVER (
    PARTITION BY customer_id
    ORDER BY order_date, order_id
    ROWS BETWEEN UNBOUNDED PRECEDING AND UNBOUNDED FOLLOWING
  ) AS vs_first
FROM orders
ORDER BY customer_id, order_date;
Some engines need the wide frame so FIRST_VALUE stays the true first row of the partition even when you also use other ordered windows. Check your dialect docs if results look "sticky" to the wrong row.
Execution order: why the CTE filter pattern exists
Rough logical order for a SELECT:
FROM/JOINWHEREGROUP BY/ aggregatesHAVING- Window functions
SELECTlistDISTINCTORDER BYLIMIT/OFFSET
Windows run after WHERE and GROUP BY. So you cannot write:
-- invalid
SELECT *
FROM orders
WHERE ROW_NUMBER() OVER (PARTITION BY customer_id ORDER BY order_date DESC) = 1;
Wrap first, filter second. Same for QUALIFY if your warehouse has it (BigQuery, Snowflake):
-- BigQuery / Snowflake style
SELECT *
FROM orders
QUALIFY ROW_NUMBER() OVER (
  PARTITION BY customer_id
  ORDER BY order_date DESC, order_id DESC
) = 1;
QUALIFY is sugar over the CTE pattern. Use it when the engine supports it; use CTEs everywhere else.
Common mistakes (and fixes)
1. Missing ORDER BY on a ranking functionROW_NUMBER() OVER (PARTITION BY customer_id) has no defined order. Always order explicitly.
2. Filtering top N in the same layer as the window
Use CTE / subquery / QUALIFY.
3. RANGE default on running totals
Prefer ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW plus a unique sort.
4. Wrong partition grain
"Latest per customer" is PARTITION BY customer_id. "Latest per customer per region" needs both keys. Wrong grain produces "almost right" dashboards that fail audits.
5. Using windows where a plain aggregate is enough
If you only need one total per region and no line detail, GROUP BY is simpler and often cheaper. Windows shine when you need row detail plus group context.
6. Index and sort cost
Windows often force a sort per partition. Help the planner with indexes that match PARTITION BY + ORDER BY access patterns on large tables, and push heavy filters into the CTE that feeds the window so partitions stay small.
Mini cheatsheet
-- latest row per key
ROW_NUMBER() OVER (PARTITION BY key ORDER BY ts DESC, id DESC)

-- leaderboard with ties (no gaps)
DENSE_RANK() OVER (PARTITION BY key ORDER BY score DESC)

-- previous value
LAG(col)  OVER (PARTITION BY key ORDER BY ts)
LEAD(col) OVER (PARTITION BY key ORDER BY ts)

-- running total
SUM(col) OVER (
  PARTITION BY key
  ORDER BY ts, id
  ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
)

-- share of group
col * 1.0 / SUM(col) OVER (PARTITION BY key)

-- whole-set total on every row
SUM(col) OVER ()
A full "analytics one-pager" query
Putting several pieces together for a customer activity view:
WITH base AS (
  SELECT
    customer_id,
    order_id,
    order_date,
    amount,
    ROW_NUMBER() OVER (
      PARTITION BY customer_id
      ORDER BY order_date DESC, order_id DESC
    ) AS recency_rn,
    LAG(order_date) OVER (
      PARTITION BY customer_id
      ORDER BY order_date, order_id
    ) AS prev_order_date,
    SUM(amount) OVER (
      PARTITION BY customer_id
      ORDER BY order_date, order_id
      ROWS BETWEEN UNBOUNDED PRECEDING AND CURRENT ROW
    ) AS lifetime_to_date,
    SUM(amount) OVER (PARTITION BY customer_id) AS lifetime_total
  FROM orders
)
SELECT
  customer_id,
  order_id,
  order_date,
  amount,
  prev_order_date,
  order_date - prev_order_date AS days_since_prev,
  lifetime_to_date,
  lifetime_total,
  recency_rn = 1 AS is_latest_order
FROM base
ORDER BY customer_id, order_date;
That single pass replaces a pile of correlated subqueries. Read it top to bottom: define the windows once, project the flags and gaps you care about, done.
What to practice next
- Rebuild three reports you already ship using only windows (latest row, top N, MoM delta).
- Force a deliberate tie and print
ROW_NUMBER,RANK, andDENSE_RANKside by side until the skip behavior is boring. - Break a running total with same-day rows, then fix it with
ROWSand a uniqueORDER BY.
Once those three feel automatic, the rest of the window catalog (NTILE, CUME_DIST, named WINDOW clauses) is vocabulary on top of the same mental model: partition, order, frame.